AI Literacy
How to spot a hallucination before it spots you
Five practical tells that an AI answer is fabricated, written for non-technical readers who want to trust their tools without being burned by them.
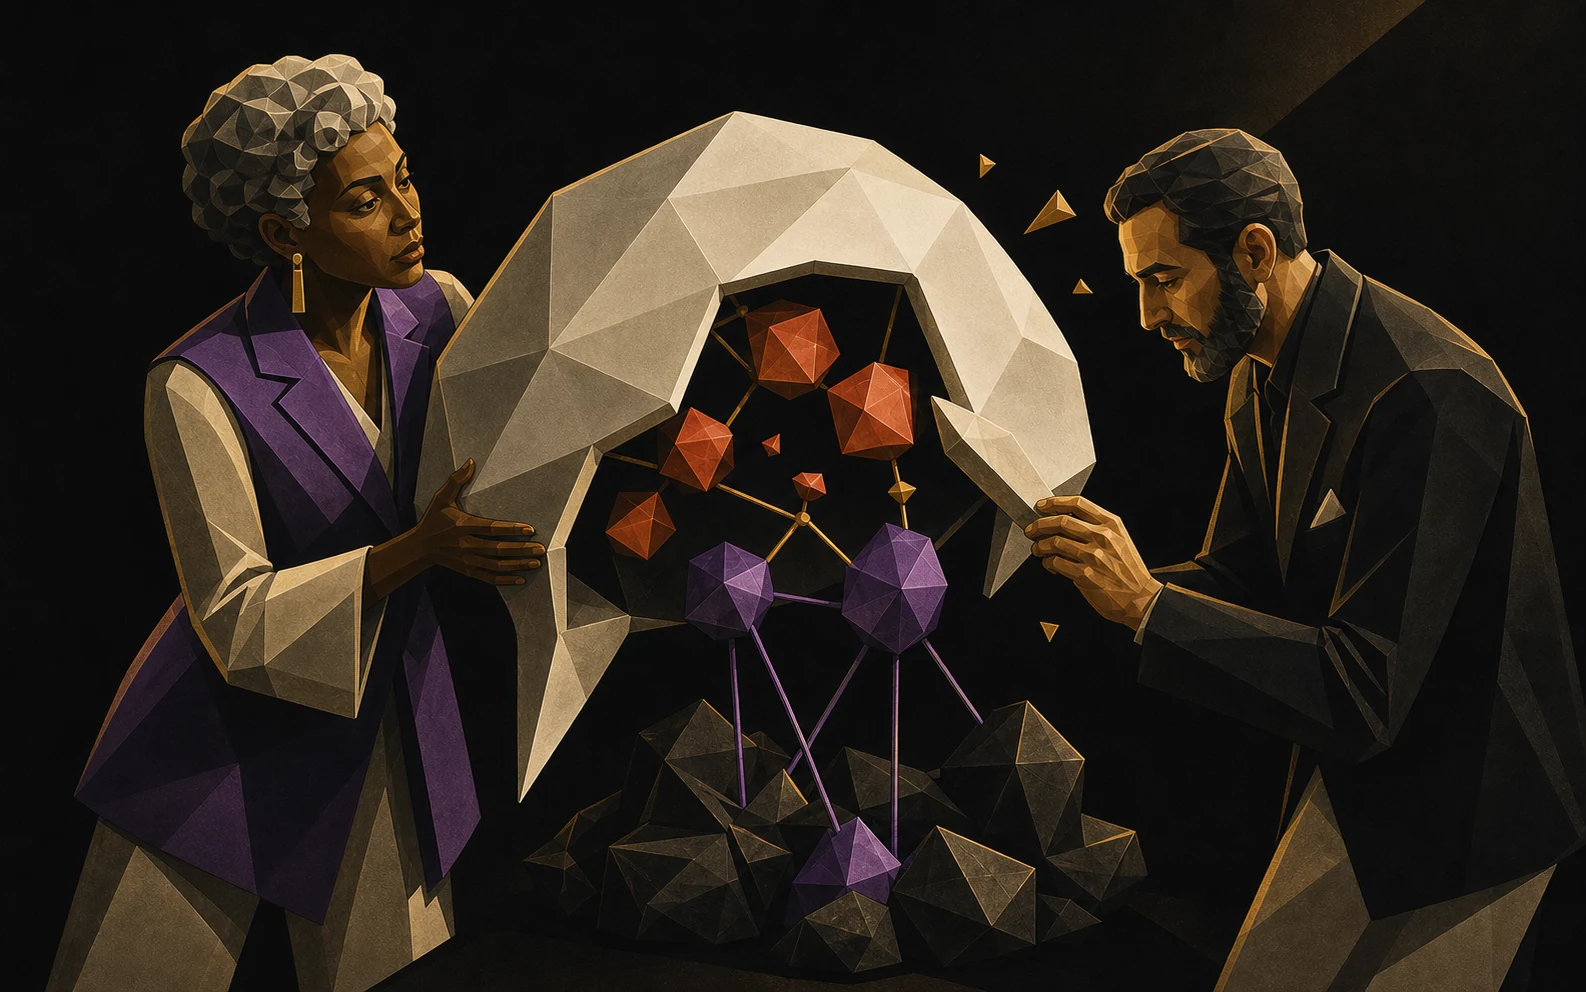
Hallucinations are not random. They follow patterns. Once you know the patterns, you can read an AI answer the same way an editor reads a press release — fast, alert, and quietly suspicious of the most fluent sentences.
Why fluency is the trap
The instinct most people apply to AI answers is the wrong one: if it sounds confident, it must be right. In practice, the opposite is more useful — if it sounds suspiciously polished on a topic where you would normally see hedging, slow down.
To understand why, look at how these tools actually work. An AI model generates text by predicting what comes next. It does not look things up in a database, and it does not “know” when it is wrong. When it produces false information — a made-up citation, a wrong date, a regulation that does not exist — it presents it with the same fluency and confidence as everything else. That is a hallucination. And spotting it is your responsibility, not the tool’s.
This is not a teething problem that the next update will fix. These models are trained to predict statistically likely text, not to retrieve verified facts. They have no internal mechanism that separates “I know this” from “this sounds right.” It is a structural feature of the technology, not a bug waiting for a patch. Mitigation strategies — retrieval-augmented generation, grounding in sources, citation-verification layers — reduce how often hallucinations occur, but they do not eliminate the risk.
The direct consequence: the AI will never flag its own mistakes. No uncertainty signal, no blinking red light. And the riskiest hallucinations are precisely the ones that look most credible: specific, precise, well-formatted. Hence the five tells that follow.
Five tells
- Specific numbers without a source. Real expertise hedges. An exact article number, a percentage with two decimal places, a date down to the day, a named official: verify it. High specificity is exactly where hallucinations hide, because it feels authoritative.
- Quotes attributed to named people. Verify, always. A plausible sentence attached to a real name costs nothing to generate and a lot to unmask. Names and quotations sit among the most dangerous zones: before you reuse a quote, find where and when it was actually said.
- Citations that read like real citations but don’t resolve. A common failure mode. The model can produce titles that sound genuine, pair a real author with a paper that does not exist, or invent a credible-looking URL. Never trust a citation without opening the source yourself, one by one.
- Smooth transitions between unrelated facts. Models love coherence, even fake coherence. Be wary, too, of answers that feel “too perfect”: exactly the regulation you hoped existed, exactly the precedent you needed. Convenience is a warning sign — slow down.
- A confident answer to a question with no public answer. That’s not knowledge — that’s confabulation. The test is simple: ask the same question a different way. If the answer changes significantly, the model was not drawing from solid ground. This reflex even exists as a prompting pattern — self-consistency, which uses the variance between answers to gauge their reliability.
Finally, keep the high-risk zones in mind: names, dates, legal references, figures, quotations, and translations of binding texts. That is where hallucinations are most frequent, and most dangerous.
The rule I keep repeating is simple: verify before you use. Every time. Build verification into the way you work, the same way you proofread a document before sending it: not as an optional extra, but as part of the job. Fluency is not accuracy, and a confident answer is not a correct answer.
One exercise I often give to drive the point home: ask your AI assistant to name three EU regulations relevant to your work. Then check each one. Does it exist? Is the title correct? Is the article number real? Write down what you find. The result surprises almost everyone.
Keep reading
AI Literacy • 2 Oct 2025 • EN
When should you start a new AI chat, and when should you continue?
The context window is a finite resource. Knowing when to reset and when to carry on is one of the highest-leverage skills in AI literacy.
AI Literacy • 4 Sept 2025 • EN
Why the way you write your prompt changes everything
A non-technical deep-dive into attention, context, and why the same model gives radically different answers to almost-identical questions.
AI Literacy • 12 Aug 2025 • EN
Not all languages are equal for AI
Tokenization is not neutral. French costs more tokens than English for the same idea, and that has direct consequences for cost, latency, and quality.