AI Literacy
Not all languages are equal for AI
Tokenization is not neutral. French costs more tokens than English for the same idea, and that has direct consequences for cost, latency, and quality.
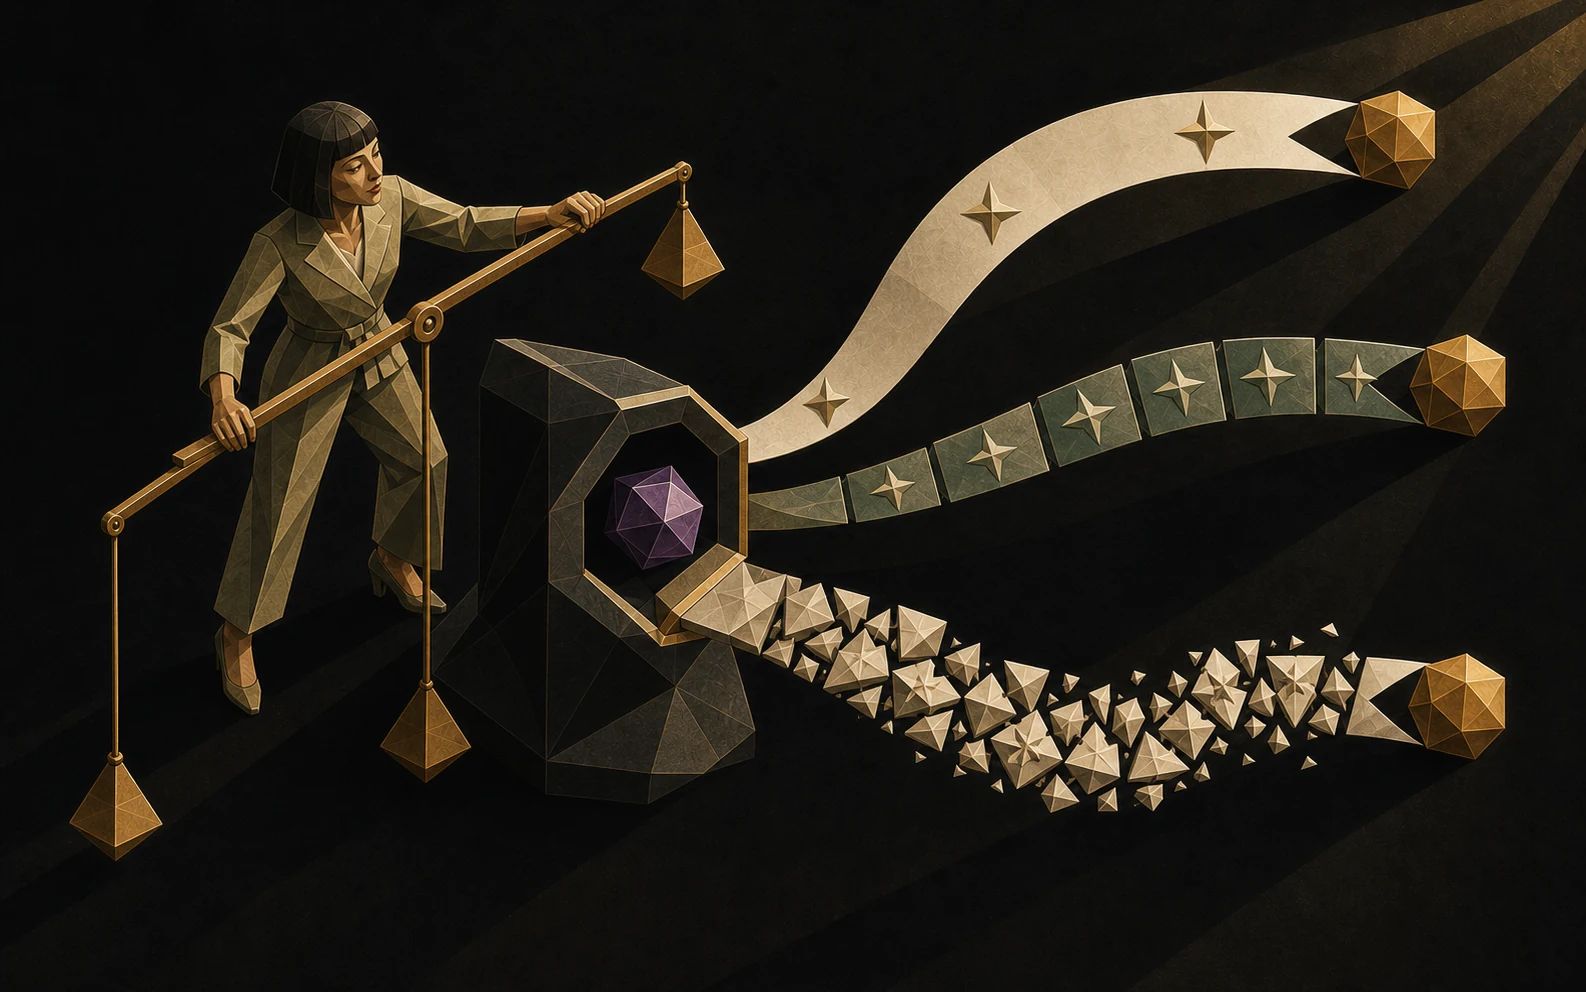
A counter-intuitive but consequential finding: writing your prompts in English is often cheaper, faster, and slightly more accurate than writing them in French — even when the final output must be in French. This article explains why, and when it matters.
Tokens, not words
Models do not see words. They see tokens — sub-word fragments produced by a tokenizer trained mostly on English text. For English, the tokenizer is efficient: roughly one token per four characters. For French, German, or Spanish, that ratio is worse. For Mandarin or Korean, worse still.
Three examples make the point. The English word “Apple”: 1 token. The French word “Élégance”: 2 tokens — “Élég” + “ance”. The Hindi greeting “नमस्ते”: up to 6 to 10 tokens, because the tokenizer has to break it down almost character by character. These counts are indicative — exact tokenization depends on the model and the tokenizer version — but the order of magnitude is structural.
None of this is random. Tokenizers are trained mostly on English: Meta reports, for instance, that Llama 3’s training dataset was roughly 95% English and code. The result is a vocabulary that is very rich and very efficient for English — and noticeably less efficient for many other languages.
The “token tax”
Researchers who have measured token consumption across languages use a telling phrase: the “token tax”. Non-English languages carry structural inflation — they cost more tokens to express the same semantic content. Think of it as an exchange rate in which English is always the reserve currency.
Two studies are the standard references here: Petrov et al., “Language Model Tokenizers Introduce Unfairness Between Languages” (NeurIPS 2023), and Ahia et al., “Do All Languages Cost the Same?” (2023). The exact numbers vary across models and tokenizer versions, but the conclusion holds: for the same content, English is the cheapest language.
Why Chinese doesn’t escape the tax
You might expect Mandarin to fare better: it is an extremely dense language, in which a single character can condense an entire concept. And yet it pays a premium. The reason is what you might call the UTF-8 encoding paradox: a Latin character takes 1 byte in memory, while a standard Chinese character takes 3. Tokenizers — often based on byte-pair encoding — learn from byte-level representations and from frequency in the training corpora. A very frequent character may fit in 1 token; a rarer one fragments into 2 or 3. In practice, semantic density offsets part of the tax — but does not cancel it.
Why it really matters: the context window
Tokens stay abstract… until you realize that every model has a context window: a hard limit on the number of tokens it can hold “in memory” at any given moment. And that limit doesn’t just cover your prompt — it also includes the response, the documents you provide, and the conversation history.
A 128,000-token window — a common size today — lets an English-speaking user load the equivalent of an entire novel. The same window, filled with a document in Arabic or Hindi, may hold only a third to a fifth of that — and for some languages barely represented in the corpora, the literature documents gaps of up to 15×. Same memory, very different capacity.
The effect on reasoning quality is direct. Complex tasks — legal analysis, synthesis, multi-step decision support — depend on the model’s ability to keep enough context to reason coherently. In “inflationary” languages, the window fills up faster: the model is forced to truncate, to compress, or to reason more shallowly. You are paying, de facto, more compute for less intelligence.
An example I often give in workshops: you upload a 20-page policy note in French and ask for a detailed analysis. Compared with the same document in English, the French version will burn more of the context window just to be read — leaving less room for the reasoning layer. The output can turn out noticeably more generic.
What to do about it
Understanding the token tax is not an argument for abandoning your working language. It is an argument for being deliberate: treating language as a prompt-engineering parameter in its own right. Here are the four strategies I apply and recommend.
1. Prompt in English for complex reasoning tasks
For tasks that require structured, multi-step reasoning — writing, analysis, classification, code generation — prompting in English is often the most token-efficient approach. The research points the same way: a 2024 EPFL study on Llama-2 suggests that models often reason through an internal representation “close to English”, even when queried in another language. The important nuance: the gap is narrowing with recent models, particularly for well-resourced European languages like French.
And nothing forces you to receive the answer in English. A prompt like “Analyze this document and identify the three main risks. Respond in French.” gives you the best of both worlds: English-grade reasoning quality, French-language output.
2. Stay concise in “expensive” languages
Every extra word in a token-expensive language consumes more of the context window. Be especially concise in German, Arabic, or other morphologically complex languages. Cut the pleasantries, the redundant context, the long introductions. Go straight to the instruction.
3. Summarize long documents before deep analysis
If you have to work on a long document in a language other than English, first ask for a concise summary — then use that summary as the basis for the analysis. This two-step approach sharply reduces token consumption before the reasoning even begins.
4. Keep English for chain-of-thought prompts
“Think step by step” techniques are extremely token-hungry: they ask the model to reason out loud. They are often more efficient in English, where they drain the context budget more slowly.
In short, the decision rule I use:
- For internal prompts, work in English when you can.
- For client-facing output, write in French (or whatever target language).
- When cost matters, run the prompt in English and translate the result.
- When nuance matters, write in the target language and accept the surcharge.
The parameter everyone forgets: model choice
The token tax is not inevitable, and the model you pick is part of the answer. European-born models are reducing the bias by training their tokenizers on better-balanced corpora: a model “born” in Europe can learn to recognize more French words as frequent units, and therefore fragment less.
EuroLLM, launched in September 2024 by an EU-funded research consortium (Unbabel, the University of Edinburgh, Instituto Superior Técnico, and Université Paris-Saclay, among others) and trained on the MareNostrum 5 supercomputer in Barcelona, aims for native coverage of all 24 official EU languages. Its tokenizer — a 128,000-subword SentencePiece BPE vocabulary trained on the full multilingual corpus — reaches a median “fertility” of 1.2 to 1.4 tokens per word across EU languages, close to English. The honest caveat: EuroLLM remains research-grade, not yet on par with the best commercial models for general reasoning. Its strength is multilingual coverage and tokenization fairness.
Mistral AI is pushing on the same front. With Mistral NeMo (2024), the French lab introduced Tekken, a tokenizer trained on more than 100 languages with a vocabulary ten times larger than its predecessor’s. Tekken is roughly 30% more efficient on several European languages — French, German, Spanish, Italian — and two to three times more efficient on Korean and Arabic. The direct consequence: the cost gap between English and French shrinks considerably on recent Mistral models. Recent tokenizers from the American labs, such as o200k_base used by GPT-4o, also correct part of the imbalance.
This is one concrete reason European AI infrastructure matters, beyond the political debates: linguistic efficiency is an infrastructure decision.
One last piece of advice, the simplest of all: test it. Take a prompt you use regularly, rewrite the instruction in English ending with “Respond in French”, then compare the two results. It is the kind of experiment that permanently changes how you work.
Keep reading
AI Literacy • 2 Oct 2025 • EN
When should you start a new AI chat, and when should you continue?
The context window is a finite resource. Knowing when to reset and when to carry on is one of the highest-leverage skills in AI literacy.
AI Literacy • 18 Sept 2025 • EN
How to spot a hallucination before it spots you
Five practical tells that an AI answer is fabricated, written for non-technical readers who want to trust their tools without being burned by them.
AI Literacy • 4 Sept 2025 • EN
Why the way you write your prompt changes everything
A non-technical deep-dive into attention, context, and why the same model gives radically different answers to almost-identical questions.