Technical
Document preparation: the key performance factor in RAG systems
In a RAG project, 80% of final quality is decided before the model: in how sources are cleaned, segmented, and indexed.
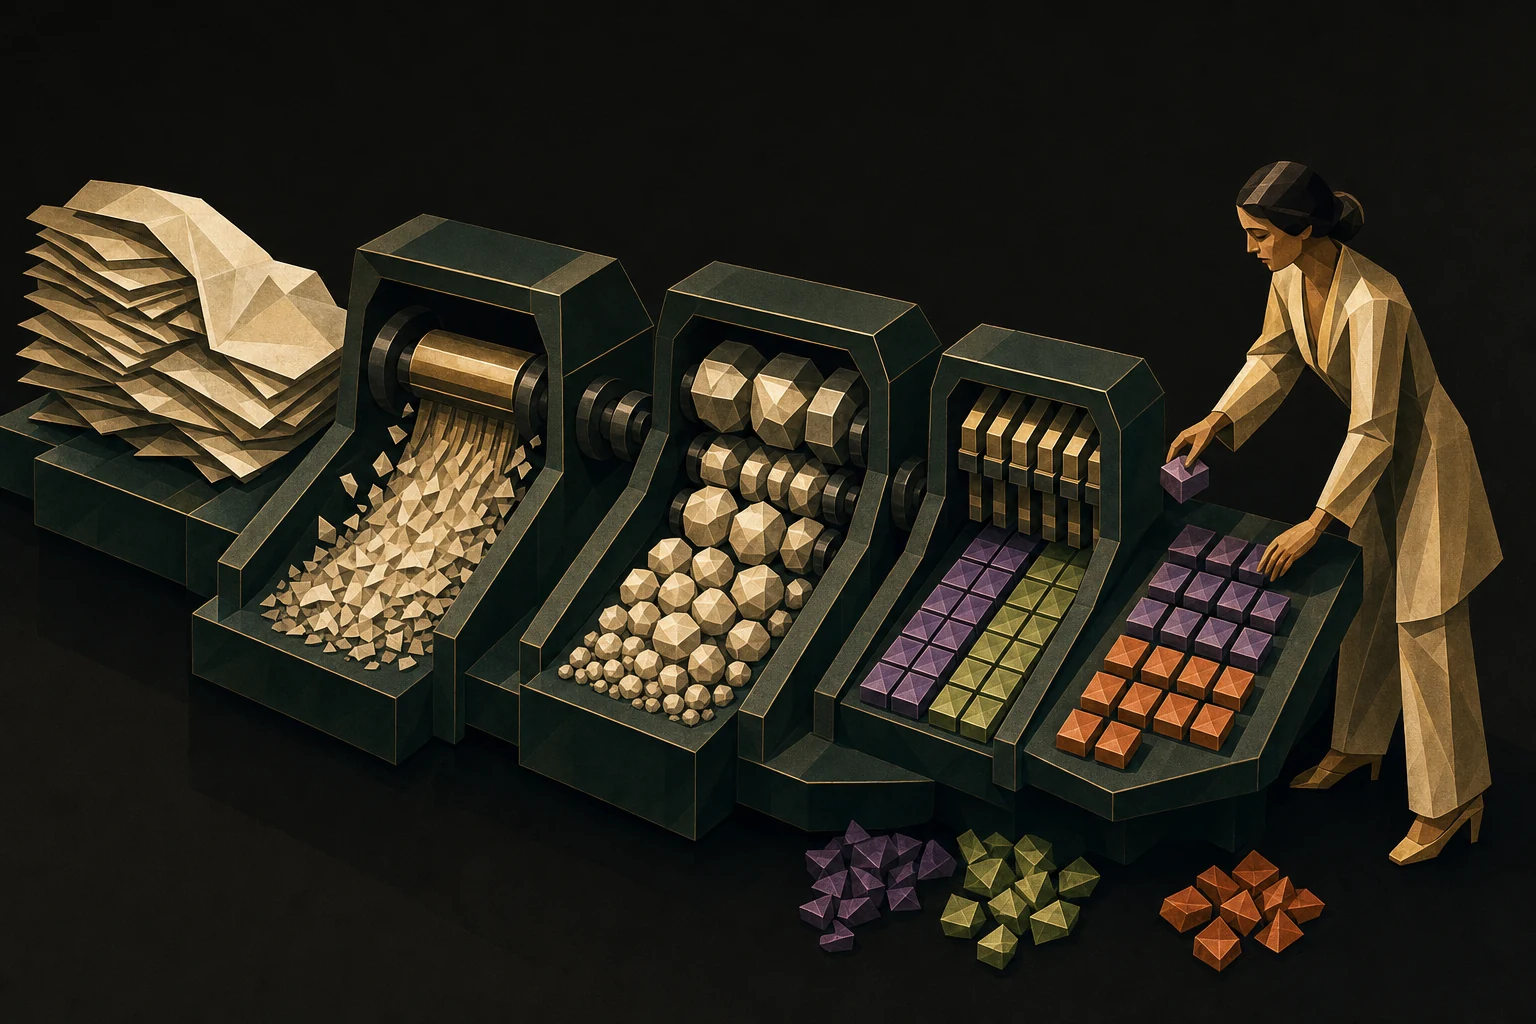
RAG demos are misleading: they work on clean, well-labelled corpora. In companies, documents are messy, contradictory, and poorly structured. This article describes what happens upstream, and why that is where quality is decided.
RAG does not fix your data
A RAG system (Retrieval-Augmented Generation) queries a knowledge base before generating an answer. That is powerful, but it inherits the quality of the base wholesale. A badly scanned PDF, a table exported without headers, an undetected duplicate: the model will faithfully reproduce the problem.
The failures I see in production almost always have the same origin: a breakdown in the document preparation chain, not in the model. The best-performing RAG systems share one trait - they invest heavily in preparing their sources. This step, often neglected in favour of model optimization, determines 70 to 80% of final answer quality depending on the project.
Here is an example I run into regularly: a financial table inside a PDF. Without proper preparation, the system reads Revenue 2023 45.7 2024 52.3 as an unstructured string of characters. It then becomes impossible to answer “What is the revenue growth between 2023 and 2024?” with any precision. With appropriate preprocessing, the table keeps its structure, and calculations and comparisons become reliable.
Preparation is therefore not just text extraction. It is about preserving meaning, context, and the relationships between pieces of information: maintaining section hierarchy, identifying structural elements (headings, lists, tables), and enriching the content with relevant metadata.
The return on investment is measurable. On well-prepared projects, answer precision is multiplied by three, inference costs are divided by five, and compliance becomes fully traceable. Conversely, a poorly prepared document produces approximate or outright wrong answers - even with the best models.
The five steps of document transformation
A systematic approach to preparation follows five steps, each adding its own value. Together, they turn unusable archives into active intellectual capital.
1. Extraction and normalization
Extraction has to handle every format in play: Word with its styles and metadata, Excel with its formulas, PowerPoint with its hidden speaker notes, HTML with its tags - not forgetting OCR for scanned documents. Normalization then unifies this heterogeneous content: encodings, date formats, whitespace, special characters. Without this step, the same information appears in multiple forms and undermines retrieval.
2. Intelligent cleaning
Not all content is equal. Repetitive headers, footers, and boilerplate legal notices pollute the index without adding value. Intelligent cleaning preserves useful information while removing the noise. One caveat: in some legal contexts, these “parasitic” elements can be crucial. Cleaning rules should be tuned per corpus, never applied blindly.
3. Semantic structuring
Corporate documents often follow recurring patterns: an annual report always has a finance section, a strategy section, a risk section. Identifying and tagging these structures lets the system navigate the corpus intelligently. Structuring can be explicit (XML tags) or implicit (intelligent chunking).
4. Contextual enrichment
Adding metadata turns a passive document into an active source. Validity date, author, department, confidentiality level, version: this information enables fine-grained filtering at query time. Enrichment can also include derived signals - sentiment analysis for audit reports, named entity extraction for contracts.
5. Optimized chunking
Chunking is the most delicate step: it directly determines the granularity and precision of answers. Chunks that are too large drown the relevant information in superfluous context - asking for the Q3 growth rate returns three pages of economic analysis. Chunks that are too small fragment the meaning - a legal definition cut in half becomes unusable.
The modern approach abandons rigid rules (512-token chunks) for an adaptive strategy: coherent technical paragraphs stay intact and preserve complex reasoning; descriptive sections tolerate splitting, provided sentences remain whole; tables and lists are never fragmented - they are atomic units of meaning.
Intelligent chunking also maintains contextual links. Each chunk carries a reference to its immediate neighbours, allowing the system to widen the context when needed: a question about a contract clause can then retrieve the definitions from the preamble or the conditions in adjacent articles. This chunk-graph approach far outperforms traditional linear splitting.
Adapting the processing to the content type
Applying the same treatment to a legal contract and a technical report guarantees mediocre results. Each document type demands a specific approach.
Structured documents (Excel, databases)
Rather than crudely linearizing tabular data, generate textual descriptions of the relationships: “Revenue for the Europe region grew 15% between Q3 and Q4 2024” is far more usable than Europe Q3 45M Q4 51.75M. Keep the raw data as well, for precise queries.
Legal and contractual documents
Hierarchy is crucial: articles, sections, and sub-sections form a tree that must be respected. Cross-references (“see article 4.2”) must be resolved, or at minimum tracked. The definitions at the start of a document condition the interpretation of everything that follows - they deserve priority treatment.
Technical and scientific documents
Formulas, graphs, and diagrams often carry the key information; failing to process them means losing the essentials. Formulas can be converted to LaTeX or MathML. Graphs need either a generated textual description or, where possible, extraction of the underlying data.
Presentations and visual materials
PowerPoint files and presentation PDFs mix text, images, and complex layouts, and the reading order is not always obvious. Layout analysis makes it possible to reconstruct the logical flow of information. As for speaker notes, often overlooked, they sometimes contain more information than the slides themselves.
Automating without losing precision
Given the volumes involved, industrializing preparation is inevitable. But automating does not mean giving up on quality: the best architectures combine automated processing with targeted controls.
Modular pipelines. Build composable processing chains where each module has a clear responsibility: extraction, cleaning, structuring. This modularity lets you adapt the pipeline per document type without rebuilding everything. It also simplifies debugging: when an answer is wrong, you can trace the problem to a specific step.
Machine learning inside the chain. Classification models automatically route documents to the right pipeline; NER (Named Entity Recognition) models enrich the metadata; layout analysis models structure complex documents. AI is not only in the final answer: it optimizes the entire chain.
Validation by sampling. Full automation is a dangerous myth. On every batch of processed documents, manually check a sample. The error patterns you detect feed back into the processing rules - this feedback loop maintains quality over time.
A path for exceptions. Not every document fits your standard pipelines: multilingual documents, exotic formats, mixed content. Handled well, these exceptions become opportunities to improve the whole system.
Measuring preparation quality
Preprocessing quality is measured with specific metrics, distinct from classic RAG metrics. Five indicators guide continuous improvement:
- Extraction completeness - what percentage of the original content is actually extracted and indexed? Diff tools can compare source and output automatically. A 95% extraction rate can look fine, until you discover that the missing 5% is the tables with the key figures.
- Structure preservation - are the hierarchical relationships maintained? A simple test: can you rebuild the original table of contents from the chunks? If not, the structuring is insufficient.
- Metadata richness - count the average number of metadata fields per document, and above all measure their actual use in queries. Unused metadata is waste; frequently requested but missing filters are missed opportunities.
- Processing time vs quality - preparation has a cost in time and resources. Sometimes 80% quality in real time beats 95% with a 24-hour delay; other times precision outweighs speed. Measure and arbitrate according to your business priorities.
- Impact on final answers - the ultimate metric remains answer quality. Set up non-regression tests: a reference set of questions with their expected answers, against which every preprocessing change is validated.
The preparation checklist
To sum up, here are the five points I systematically verify before indexing a corpus:
- Cleaning - quality OCR, footer removal, encoding normalization.
- Segmentation - semantic chunking, not mechanical slicing.
- Metadata - date, source, status (current / outdated).
- Deduplication - two versions of the same document means two contradictory votes.
- Evaluation - a reference question-and-answer set before any production launch.
Document preparation is not one technical step among others. It is the foundation on which the entire value of your RAG system rests - the organizations that have understood this invest as much in their preprocessing pipeline as in their models.
Keep reading
Technical • 14 Jul 2026 • EN
Your AI agents don't have a goal problem. Your organization does.
Hand your corporate objectives to an AI agent and it fails instantly, for reasons an engineer can name precisely. The same reasons your people have been quietly absorbing for years.
Technical • 30 Jun 2026 • EN
From prompts to loops: the four-layer shift your AI strategy hasn't caught up with
Prompt engineering, context engineering, harness engineering, loop engineering. Each layer vendors sell as a technical specialty is an organisational discipline your company needed before AI existed.